Let's talk
Menu
PRE-ORDER
PRE-ORDER
1
PRE-ORDER
Let's talk
Menu
Turn memory into inference capacity.
Kelvin adds dedicated capacity for long-context inference.
SHARE INTEREST
SHARE INTEREST
1
SHARE INTEREST
GENERATION 01
NORMAL INFERENCE SYSTEMS
COMPUTE-IN-MEMORY
PRODUCT
Energy-efficient inference, built to scale.
System Configurations
Air-cooled systems in server, appliance and rack configurations.
Server
A complete system for long-context inference, with compute-in-memory acceleration designed for high token throughput and energy efficiency.
Memory Compute Appliance
Expands KV-cache capacity or accelerates decode with compute in memory, extending GPU-based systems for workloads limited bycapacity or throughput.
Rack
Brings Kelvin Servers and optional Memory Compute Appliances into heterogeneous infrastructure, scaling from single- to multi-rack deployments.
KELVIN WORKLOADS
Accelerate AI inference.
AI inference
Long-context inference
Disaggregated inference
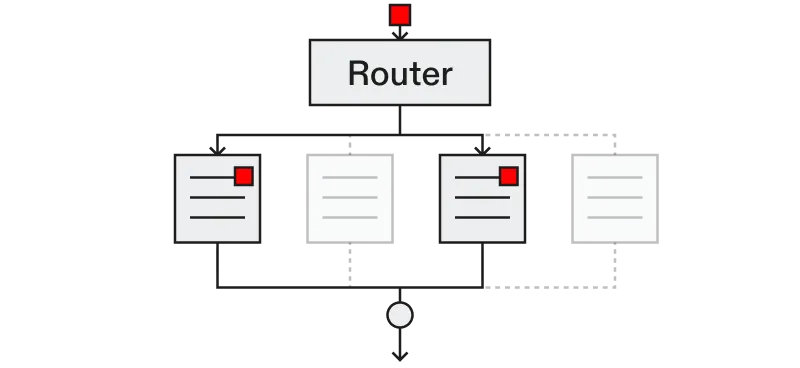
Mixture-of-experts models
High-concurrency inference
INTEGRATION
Model-aware inference, across systems.
Kelvin’s integration roadmap spans heterogeneous serving with GPUs and standalone systems for both prefill and decode.
Model and serving fit
Dynamic workload placement based on model requirements, performance and capacity.
PRE-ORDERS
Add dedicated long-context inference capacity to your infrastructure.
A conditional purchase order reserves priority capacity in the first available delivery window for your configuration.
01
DEFINE YOUR WORKLOAD
02
ALIGN THE CONFIGURATION
03
RESERVE PRIORITY CAPACITY
Out team will align delivery timing during solution scoping.
Work email*
Company*
Brief workload description
1
SHARE INTEREST
Thank you!
Your submission has been received.
Oops! Something went wrong while submitting the form.